Grok 4.7 is now available in ThinkReview
Grok 4.7 is now available in ThinkReview
We're excited to announce that Grok 4.7 is now available in ThinkReview. On September 21, SpaceXAI released Grok 4.7 as its most capable model for coding and knowledge work: a larger base than Grok 4.6, trained longer on tasks that take many hours, and served at the same price and speed as Grok 4.6. You can use it today for AI-powered code reviews on GitHub, GitLab, Azure DevOps, and Bitbucket.
What is Grok 4.7?
Grok 4.7 is the next Grok after 4.6. SpaceXAI describes a bigger base model, a longer reinforcement-learning run on a harder mix of problems, and better habits around checking its own work and holding a long context. It was also trained to understand the Grok Bot harness, which shows up in conversational and knowledge-work tasks as well as code.
Highlights from the launch:
- Same list price as Grok 4.6 — $2 / $6 per million input and output tokens. A fast variant runs at twice the output speed and twice that price.
- Stronger on long coding tasks — 46.3% on CursorBench 4.0, up from 40.4% for Grok 4.6 High, and ahead of GPT-5.6 Sol Max at 41.7%.
- Better at checking its own work — Useful when a review should trace a failure past the first suspicious line.
- Knowledge work moved up with the code — GDPval Elo of 1,695 at xHigh, versus 1,605 for Grok 4.6 High.
- Available beyond the Grok app — Cursor, Grok Build, the Grok API, and third-party coding harnesses. And now inside ThinkReview.
The launch line "twice as fast, at half the price of comparable models" is about the class around it. GPT-5.6 Sol is listed at $4 / $20 and Fable 5.1 at $10 / $50. Against Grok 4.6, price and speed stay put. You get the new model on the bill you already know.
Charts from the announcement
These figures are from SpaceXAI's post. They are the shortest way to see where 4.7 sits.
On CursorBench 4.0, which stresses longer-running coding tasks, Grok 4.7 lands on the price-performance frontier: close to the top scores, far down the cost axis.
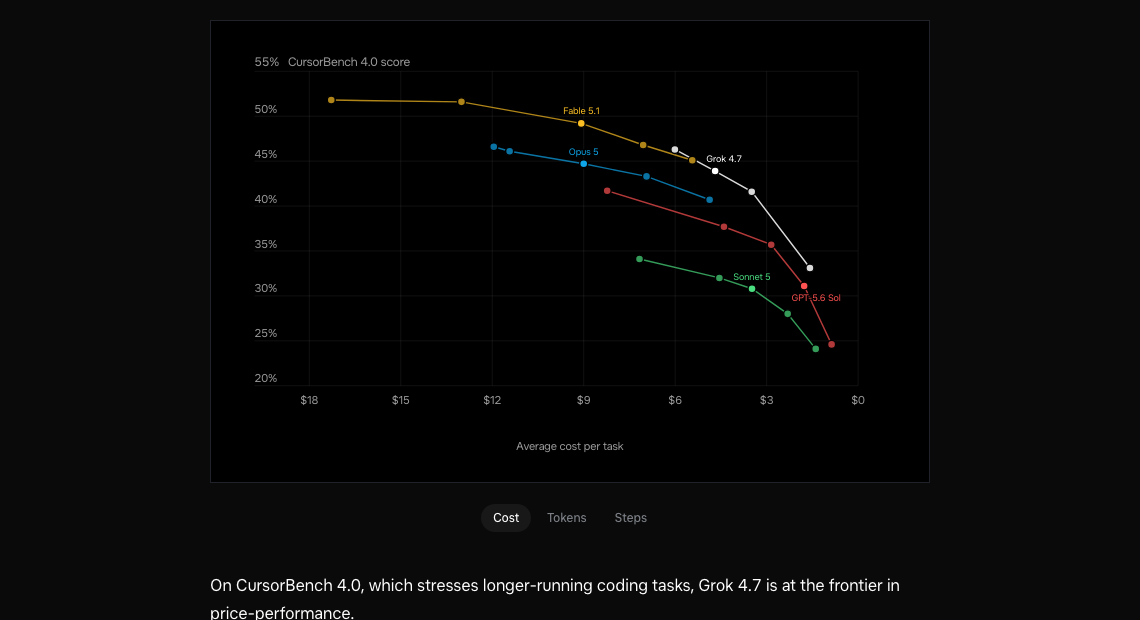
Source: Introducing Grok 4.7, SpaceXAI.
The comparison table is the one to read before you switch a review default. Grok 4.7 xHigh keeps Grok 4.6's $2 / $6 rates and leads 4.6 on every row SpaceXAI published. The DeepSWE 71.0% mark is a high-effort score.
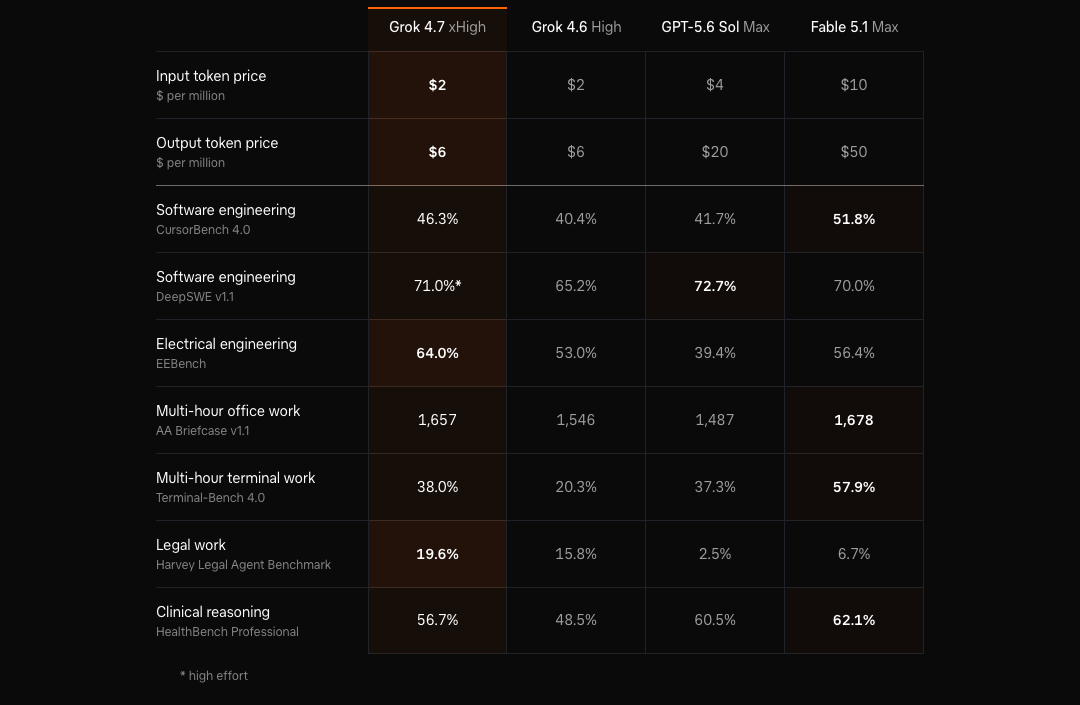
Source: Introducing Grok 4.7, SpaceXAI. The asterisk on DeepSWE marks high effort.
Professional knowledge work moved in the same direction. On GDPval, Grok 4.7 xHigh scores 1,695, between Fable 5.1 Max (1,735) and Grok 4.6 High (1,605).
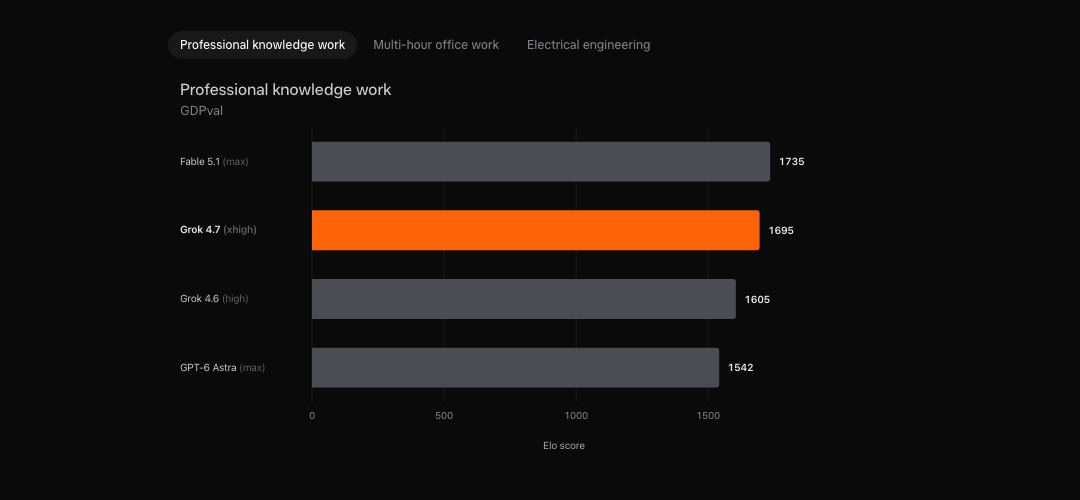
Source: Introducing Grok 4.7, SpaceXAI.
Why Grok 4.7 is a strong fit for code review
Pull request review is a long-horizon job. The model reads a diff, follows related files, and writes findings a human reviewer will actually act on. That is the workload this training run was weighted toward.
- Sharper first passes on hard diffs — The CursorBench and DeepSWE lifts over Grok 4.6 are the coding numbers that map to bugs, regressions, and contract breaks.
- Stays with multi-hour traces — Terminal-Bench 4.0 goes from 20.3% on Grok 4.6 High to 38.0% on Grok 4.7. Reviews that have to follow a failure across services benefit from that.
- Checks itself before it comments — SpaceXAI calls out better verification and longer-context handling. That is how you get fewer confident-but-wrong notes.
- Frontier coding without a new price — Sol-class cost on the chart, Grok 4.6's token rates on the invoice. Use it when you want the upgrade on the PRs you already review with Grok.
- Same ThinkReview loop — Fetch context, reason, comment. Pair it with repository-level context when the real bug lives outside the hunk.
Benchmarks are not your team's review bar. Treat severity labels as input, and keep the final call with the person who owns the merge.
How to use Grok 4.7 in ThinkReview
- Open ThinkReview settings — Click the extension icon and go to Settings or Model selection.
- Choose Grok 4.7 — Select it from the model dropdown for your reviews.
- Run a review — Open any pull request or merge request and start ThinkReview with your chosen model.
Manage your catalog in Model Selection on the ThinkReview portal.
Where it works
Same as always: GitHub, GitLab, Azure DevOps, and Bitbucket Cloud. One extension, one workflow — now with SpaceXAI's Grok 4.7.
If you try Grok 4.7 on real PRs and have feedback, we'd love to hear it — open an issue on GitHub or reach out via thinkreview.dev.
Ready to try Grok 4.7 on your next PR? Install ThinkReview or manage your models in the portal.
Model details and charts reference SpaceXAI's Grok 4.7 announcement.